Preview for Pay Once, Not Per Task: Four Repeated Costs Comet 1.1.0 Stopped Paying

Pay Once, Not Per Task: Four Repeated Costs Comet 1.1.0 Stopped Paying

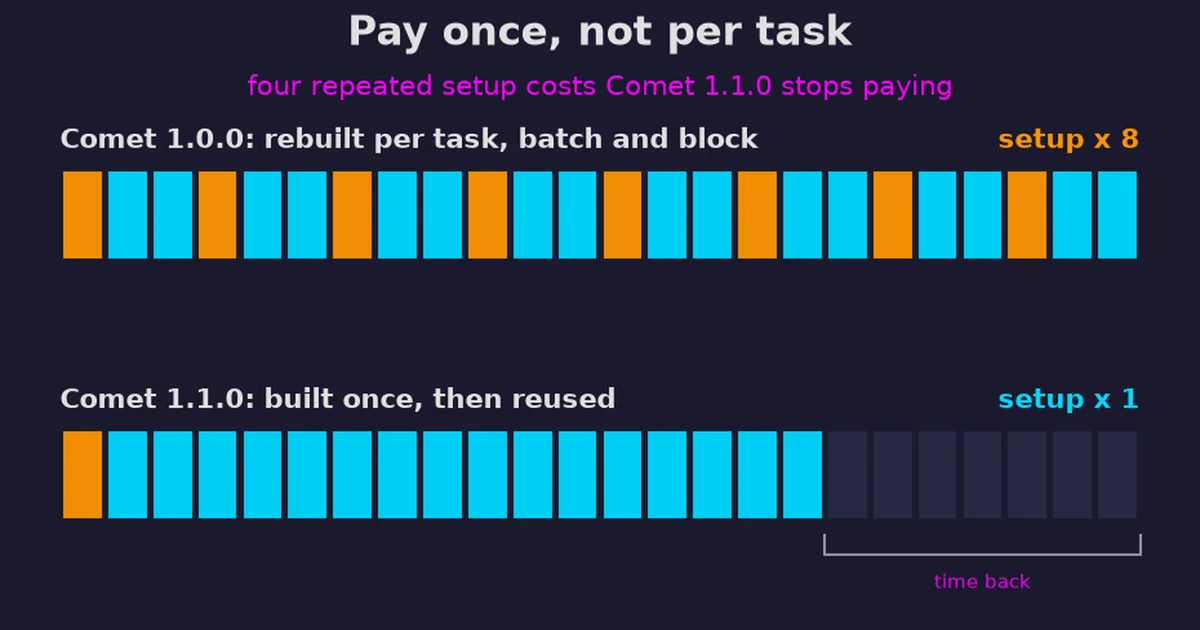
Apache DataFusion Comet 1.1.0 is out, with 14 of my PRs in it. Four of them fix the same kind of waste: work that gives the same answer every time but was being redone for every task, batch or shuffle block. Here is what each one changed, what the benchmarks really show, and the correctness fix I'd point to first.

apache spark datafusion comet rust scala data engineering performance open source
Read more
Preview for Databricks Never Skips a Page. Its Writer Does Not Even Write Them

Databricks Never Skips a Page. Its Writer Does Not Even Write Them

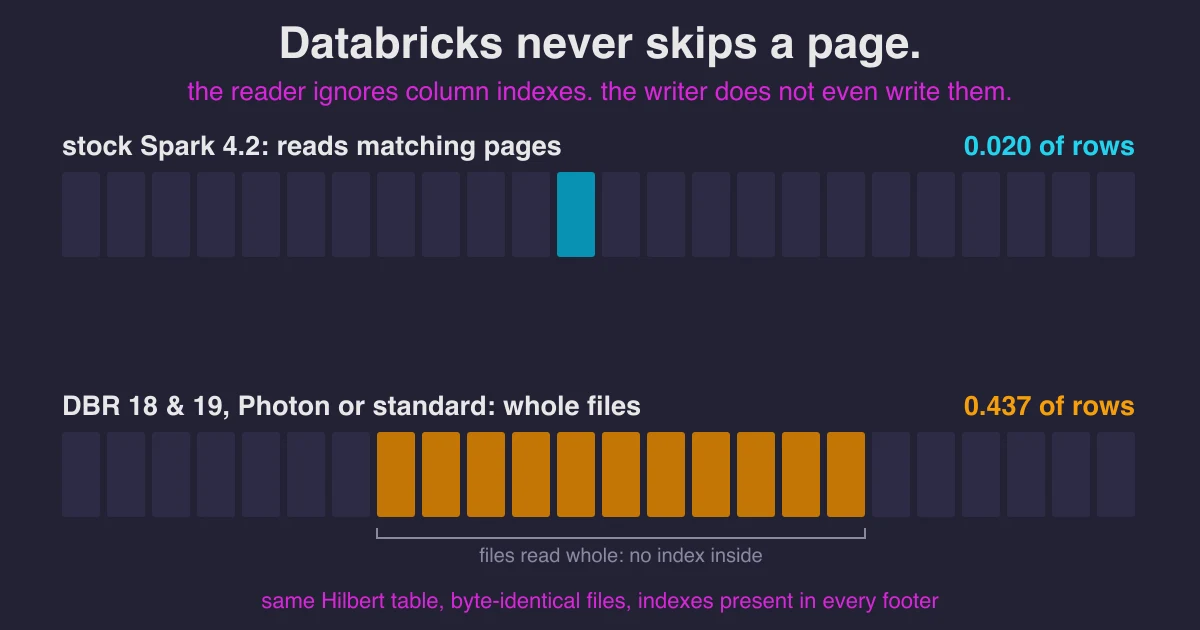
Databricks' parquet writer emits no column indexes, and none of its four reader configurations evaluates them on files that carry them. Measured across three layouts and six readers at 1 TB, on identical 224-core fleets, down to the parquet footers. Liquid clustering turns out to be the workaround: a kd-tree whose leaves are the file boundaries, because file min/max is the only statistic the platform can act on. The open reader stack beats its best case on every query family at a tenth of the bytes.

databricks photon liquid clustering apache spark delta lake parquet datafusion comet data engineering performance
Read more
Preview for Comet Falls Back to Spark on Every Delta Table. I Wrote the PR That Fixes It

Comet Falls Back to Spark on Every Delta Table. I Wrote the PR That Fixes It

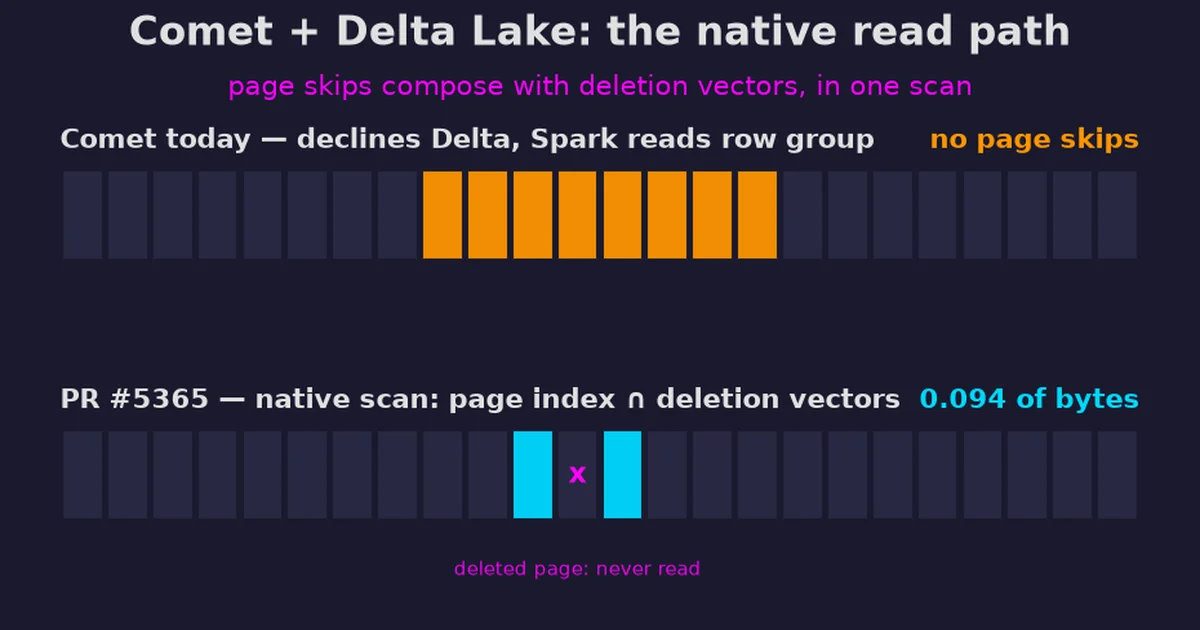
DataFusion Comet declines every Delta table over a one-line format check, giving up native execution and all parquet pruning. PR #5365 adds a native Delta read path that inherits row-group and page-index pruning for free, and applies deletion vectors inside the scan itself. Measured at 1 TB: the Delta arm is indistinguishable from raw parquet.

apache spark datafusion comet delta lake parquet rust data engineering performance open source
Read more
Preview for Your Parquet Column Indexes Are Being Ignored on EMR and Glue

Your Parquet Column Indexes Are Being Ignored on EMR and Glue

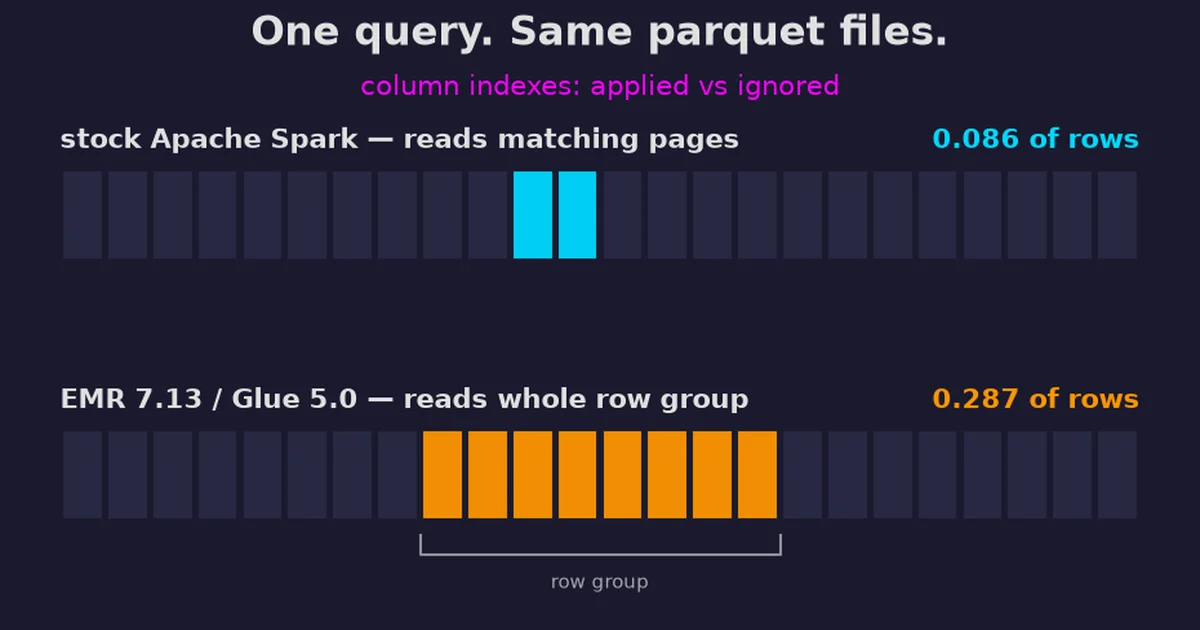
A benchmark that made no sense led to a four-environment A/B test proving the AWS Spark runtime's vectorized reader skips row groups but never pages, plus a 120-line MWE anyone can run to verify it.

apache spark parquet emr aws glue data engineering performance delta lake benchmarking
Read more